Guide · QA + AI series · 21/31 · November 13, 2026 · 7 min read
Testing RAG: retrieval, faithfulness and answer, separately
How to test a RAG system in three layers so that, when it fails, you know whether the problem is retrieval, generation or the knowledge base.
A RAG system answers questions by first searching your documents and then generating an answer with what it found. When it answers badly, the usual reaction is to tweak the prompt. Sometimes that works. Often it doesn't, because the problem came earlier: the right document never reached the model, and no instruction can make up for that.
Testing a RAG end to end, with a single metric, mixes two different systems: a search engine and a generator. This guide splits them into three layers measured separately, and adds negative cases, where the correct answer is admitting the information isn't there. The result is a diagnosis that says where to fix things, not just that something is wrong.
How it fits together
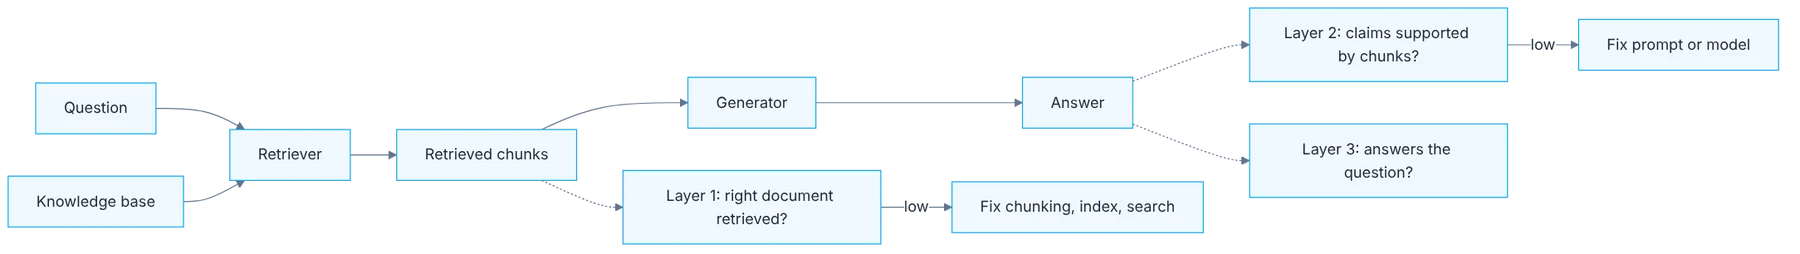
Show the diagram as text
question ─▶ retriever ◀── knowledge base
                ▼
        retrieved chunks ─────▶ Layer 1: right document retrieved?
                ▼                    └─ low ▶ fix chunking / index / search
            generator
                ▼
             answer ──────────▶ Layer 2: claims supported by chunks?
                │                    └─ low ▶ fix prompt / model
                └─────────────▶ Layer 3: answers the question, matches expected?
Requirements
- Python 3.10+ and a RAG app exposing the answer and the retrieved chunks.
- 20 questions with expected answer and source document.
- DeepEval defaults to an OpenAI model as judge (needs
OPENAI_API_KEY); its docs explain how to use another.
Setup
pip install deepeval
deepeval test run tests/test_rag.py
from deepeval import assert_test
from deepeval.test_case import LLMTestCase
from deepeval.metrics import (
ContextualRecallMetric, FaithfulnessMetric, AnswerRelevancyMetric,
)
from my_app import ask # returns (answer, retrieved_chunks)
def test_refund_policy():
question = "How many days do I have to request a refund?"
answer, chunks = ask(question)
case = LLMTestCase(
input=question,
actual_output=answer,
expected_output="30 days from delivery.",
retrieval_context=chunks,
)
assert_test(case, [
ContextualRecallMetric(threshold=0.8),
FaithfulnessMetric(threshold=0.9),
AnswerRelevancyMetric(threshold=0.8),
])Step by step
1. Layer one: retrieval
Layer 1, retrieval: for each question, check whether the right document shows up among the retrieved chunks. It's deterministic and needs no model.
For each question in the dataset, note which document holds the answer. The test checks whether that document shows up among the retrieved chunks. No model is needed to evaluate it: it's a comparison of identifiers, deterministic and fast. This metric is the system's ceiling. If the right chunk shows up for seven questions in ten, the final answer can't be right with grounding in more than seven. Starting here avoids weeks of adjustments in the wrong place.
2. Layer two: faithfulness
Layer 2, faithfulness: every claim in the answer must be supported by the retrieved chunks. This is where fabrications get caught.
Faithfulness asks whether every claim in the answer is supported by the retrieved chunks. It doesn't evaluate whether the answer is true in general, but whether it comes from the context the system had. This is where fabrications get caught: a fact the model added from prior knowledge, an altered figure, a condition the document doesn't mention. It's measured with a judge that breaks the answer into claims and verifies each one. For figures and dates, add deterministic checks.
3. Layer three: answer
Layer 3, answer: does it answer what was asked and match what's expected?
Only in the third layer do you evaluate whether the answer addresses what was asked and matches what's expected. An answer can be faithful to the context and still useless: it talks about the topic, quotes the document well and doesn't answer the specific question. Or it can answer correctly from general knowledge without relying on your documents, which is a different risk. That's why the three layers are read together: each combination of results points to a different problem.
4. Negative cases
Add negative cases: questions whose answer isn't in the knowledge base. The system must say it doesn't know.
Add questions whose answer isn't in the knowledge base. The expected behavior is for the system to say so, instead of assembling a plausible answer from vaguely related chunks. It's the case that does the most damage in production and the least tested, because datasets tend to be built from existing documents. Also include nearly covered questions: the document discusses the topic but doesn't carry the specific fact being asked for.
5. Diagnose per layer
Diagnose per layer: low retrieval is fixed in chunking, index or search; low faithfulness is fixed in prompt or model. Changing the prompt doesn't fix bad retrieval.
With the three metrics separated, each fix has its place. Low retrieval is fixed in chunk size, the index or the search. Low faithfulness with good retrieval is fixed in the prompt or by changing models. A low answer score with the other two high is usually a format or instructions problem. The practical rule is not to touch the prompt until you've confirmed retrieval works: changing the prompt doesn't fix a search that doesn't find.
6. Metrics in CI
Bring the three metrics into CI with thresholds and track them on every document change.
Bring the three metrics into the pipeline with a threshold for each, and run the eval every time documents change, not just code. In a RAG, the knowledge base is part of the system. A new document contradicting another, or a folder reorganization, can lower retrieval without anyone having touched a line. Record how the metrics evolve with each content change so you can locate when a drop began.
Illustrative example
An internal assistant answers questions about company policies. The team builds forty questions with their source document and ten negatives. First measurement, with illustrative figures: retrieval 65%, faithfulness 92%, answer 60%. The team had been tuning the prompt for two weeks. The numbers show the generator is faithful to what it receives and that the problem lies in search. They check and find chunks were cutting tables in half. They change the chunking strategy and retrieval rises to 90%; the answer score, to 84%, without touching the prompt. On the negatives, three out of ten still make things up. That one does get fixed with an instruction.
Common mistakes
- Measuring only the final answer and not knowing which layer fails.
- Tuning the prompt when the problem is retrieval.
- Not including questions with no answer in the knowledge base.
- Running the eval only when code changes and not documents.
Checklist: how to know it is done
- Each question has its source document noted.
- Retrieval, faithfulness and answer are measured separately.
- The dataset includes negative and nearly covered cases.
- The eval runs in CI on document changes.
Where AI fell short
With the right source in context, it still alters figures. Faithfulness is measured, not assumed.
Frequently asked questions
How many chunks should I retrieve?
It's the same question as the K from day nineteen, and it's answered the same way: by measuring retrieval and final answer at different values. More chunks raise the chance of including the right one and also the noise the model receives.
Is faithfulness measured by a judge reliable?
As reliable as its calibration. Apply the day sixteen method: hand-label a sample of answers as faithful or not and measure agreement. For hard facts such as amounts and dates, don't depend on the judge.
Does it help if I use an off-the-shelf RAG product?
Yes. Even without control over search, you can measure the three layers from outside if the product exposes which chunks it used. If it doesn't expose them, ask for it: without that information you can't tell a search problem from a generation problem.
Day 21 of 31 of the 31 days of QA + AI series. Commands and versions reviewed in November 2026: rerun them before relying on them, AI tooling changes fast.
← Previous: Prompt regression: version, compare and don't break what worked
Next: A model for security testing (1): threat modeling with the OWASP LLM and Agentic Top 10 →