Guide · QA + AI series · 11/31 · November 13, 2026 · 6 min read
Playwright Test Agents: planner, generator and healer in action
The full planner, generator and healer cycle in a real repo, and the two points where a person must step in.
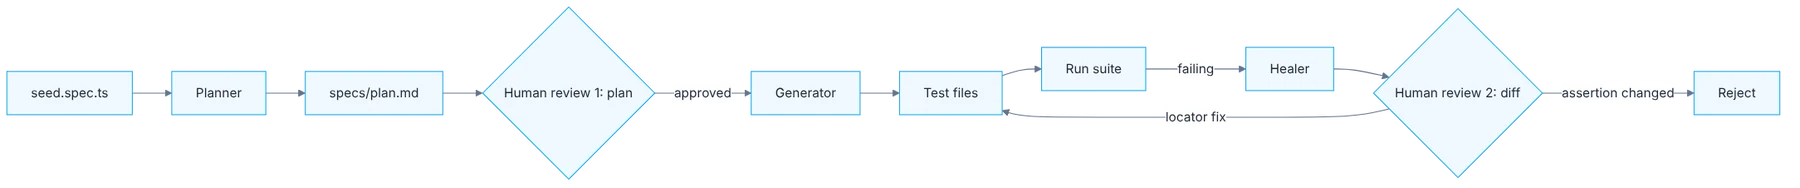
Yesterday you built the explore, plan and generate flow by hand, with your own prompts. Playwright ships that same flow packaged as three agents with separate responsibilities: one plans, one generates and one heals. The advantage isn't that they're smarter, but that each has narrow instructions and leaves an artifact the next one uses.
The risk comes packaged too. A system that repairs tests on its own can leave the suite green for the wrong reason. This guide walks through the three agents and marks the two points where a person must step in no matter what: before generating and after healing. Without those two reviews, what you gain in speed you lose in trust.
How it fits together
Show the diagram as text
seed.spec.ts ▶ Planner ▶ specs/plan.md
                             ▼
                  human review 1: the plan
                             ▼ approved
                         Generator ▶ tests/*.spec.ts ▶ run suite
                                                          │ failing
                                                          ▼
                                                        Healer
                                                          ▼
                                             human review 2: the diff
                                               ├─ locator fix       ▶ accept
                                               └─ assertion changed ▶ reject
Requirements
- Up-to-date Playwright (agents ship since version 1.56).
- A coding agent: Claude Code, VS Code with Copilot or OpenCode.
Setup
npm i -D @playwright/test@latest
npx playwright install chromium

# pick your agent loop
npx playwright init-agents --loop=claude
# npx playwright init-agents --loop=vscode
# npx playwright init-agents --loop=opencode
Step by step
1. Initialize and commit
Upgrade Playwright and run init-agents with your agent's loop. It generates the three agent definitions, a seed.spec.ts, the specs/ folder and the test MCP server config. Commit everything.
The init command generates the three agent definitions for the loop you use, a seed test, the plans folder and the test MCP server config. Commit all of that together. The definitions are instructions in text: it's worth reading them once to understand what each agent will do and with which tools. Being in the repo, the whole team uses the same ones, and any adjustment you make stays in history just like a code change.
2. The seed test
Write the seed test: it leaves the page in the initial state every flow needs (for example, logged in as a test user).
The seed is an ordinary test that leaves the application in the state every flow starts from: session started, minimum data loaded, initial screen. The agents run it before exploring or generating, so it also serves as a style example: generated tests tend to resemble it. Write it with the same care as your best test. If it uses role-based locators and clear fixtures, whatever comes next inherits that. If it's sloppy, that too.
3. Planner and the first intervention
Planner: ask it to explore a flow and save the plan in specs/. Intervention 1: review the plan before generating anything.
The planner explores the application starting from the seed and writes a Markdown plan into the plans folder: scenarios, steps and expected results. This is the first human intervention, and it's the cheapest in the whole chain. Read the plan before generating anything. Remove scenarios that add nothing, add the ones that depend on business rules and fix expected results the planner assumed. Every error you let through gets multiplied in code.
4. Generator
Generator: ask for the tests from the approved plan. It checks selectors against the live page while writing.
The generator takes the approved plan and writes the tests. The difference from a classic generator is that it verifies against the live page: it executes the steps while writing and checks that each locator finds its element. That's why the result usually runs first time. Even so, review the assertions. A test can navigate the whole flow correctly and end up verifying something trivial, such as the URL having changed, instead of the rule the scenario meant to prove.
5. Healer and the second intervention
Healer: break a locator on purpose and run the healer. Intervention 2: review the diff. Fixing a locator is fine; changing an assertion is not.
Break a locator on purpose, for example by renaming a button, and run the healer. It will run the test, see the failure, inspect the page and propose a fix. This is the second intervention: reviewing the diff. There are two kinds of change. Updating a locator because the interface changed is legitimate maintenance. Modifying or removing an assertion so the test passes is hiding a possible defect. The first gets accepted; the second gets rejected and investigated.
6. Regenerate on every upgrade
On every Playwright upgrade, rerun init-agents in the same PR to regenerate the definitions.
The agent definitions are tied to the Playwright version: available tools and instructions change. When you upgrade, rerun the initialization in the same pull request and review what changed in the definitions. If you had made your own adjustments, you'll have to reapply them, so it's worth documenting them in a separate file. Leaving old definitions with a new version produces failures that are hard to diagnose.
Illustrative example
A team tests the user sign-up flow. The planner proposes nine scenarios. In review they remove two repeated ones and add one it couldn't know: emails from a blocked domain must be rejected. The generator writes eight tests and seven pass first time. A week later a redesign changes a button's text and four fail. The healer fixes the four locators. In the diff, three changes are locator-only. The fourth also changed an assertion from "shows the error" to "the button is visible". They reject that change, investigate and discover the error message had disappeared in the redesign.
Common mistakes
- Generating tests without having read and corrected the plan.
- Accepting the healer's result because the suite turned green.
- Writing a sloppy seed test that every later test imitates.
- Upgrading Playwright without regenerating the agent definitions.
Checklist: how to know it is done
- The definitions, the seed and the config are committed.
- The plan was reviewed by a person before generating.
- Each generated test has an assertion that proves a rule.
- The healer's diff was reviewed separating locators from assertions.
Where AI fell short
The healer can turn a test green by modifying the assertion. A healed test with an unreviewed diff is a false green.
Frequently asked questions
Can I run the healer automatically in CI?
You can, as long as its output is a pull request and not a direct commit. Automatic repair without review is the fastest way to pile up tests that no longer prove anything. The value is in it proposing the fix, not approving it.
How many scenarios should I ask the planner for?
One flow at a time. Asking for "the whole application" produces long plans nobody reviews well. With one flow, the plan fits on a screen and review takes minutes, which is what makes the first intervention really happen.
Do generated tests stay tied to the agents?
No. They are ordinary Playwright tests, in your repo, running with the usual runner. You can stop using the agents and the tests keep working. What does stay tied to the version are the definitions.
Day 11 of 31 of the 31 days of QA + AI series. Commands and versions reviewed in November 2026: rerun them before relying on them, AI tooling changes fast.
← Previous: Playwright MCP: an agent that browses your app and proposes tests
Next: Failure triage with LLMs: from 40 red tests to 3 root causes →