Guide · QA + AI series · 31/31 · November 13, 2026 · 7 min read
Capstone: the full AI quality pipeline and your 2027 roadmap
The previous 30 days tied into a single pipeline, a 12-point checklist to self-assess and a 90-day plan with public evidence.
For thirty days you saw separate pieces: a rule for delegating, an eval, a configured agent, a threat model, a load test, a gate. Each solves a concrete problem. The greater value appears when they connect, because that's where they stop being experiments and become a quality system for software that uses AI.
This last day adds no tools. It assembles the full map, asks you for an honest assessment of what you really have working and helps you choose what to build first. The series doesn't expect you to implement all twelve pieces. It expects you to know which ones matter to your product, in what order, and to be able to show evidence of progress three months from now.
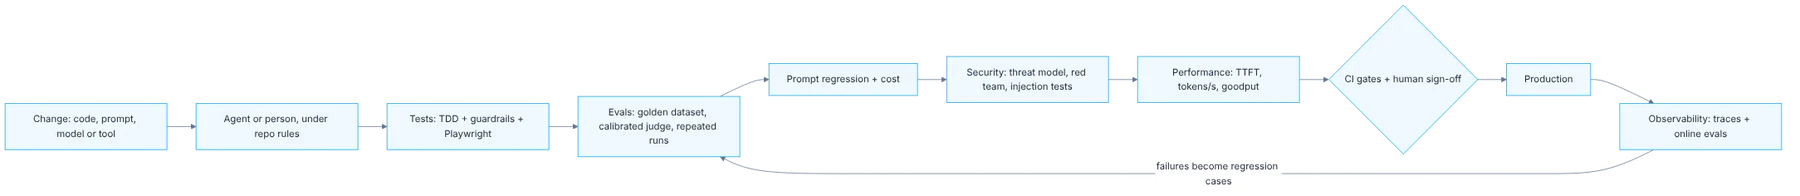
How it fits together
Show the diagram as text
change: code, prompt, model or tool
   ▼
agent or person, working under repo rules
   ▼
tests: TDD + guardrails + Playwright
   ▼
evals: golden dataset, calibrated judge, repeated runs ◀──────────────┐
   ▼                                                                  │
prompt regression + cost                                              │
   ▼                                                                  │
security: threat model, red team, injection tests                     │
   ▼                                                                  │
performance: TTFT, tokens/s, goodput                                  │
   ▼                                                                  │
CI gates + human sign-off ▶ production ▶ observability ───────────────┘
                                         (failures become regression cases)
Requirements
- The
qa-ai-labrepo with whatever you built during the series. - The skills matrix from day 2.
12-piece checklist
- Delegation rule: verifiable, cheap to review, reversible (day 1).
- Repo with rules for agents, tools and permissions (day 9).
- Tests written by people, implementation by agents, with guardrails (days 13 and 14).
- Playwright agents with plan and diff review (days 10 and 11).
- Eval harness with a versioned prompt (day 8).
- Pinned model versions and a calibrated judge (days 15 and 16).
- Golden dataset with dev, test and regression (day 17).
- Repeated runs, ranges and cost per call (days 18 and 19).
- Prompt regression before every change (day 20).
- Threat model, red teaming and injection tests (days 22 to 24).
- Performance targets and tests with token metrics (days 25 to 27).
- CI gates, reproducible infra and observability (days 28 to 30).
Step by step
1. The full journey
Walk the diagram end to end: a change enters through the repo, produced by an agent or a person, and goes through tests, evals, security and performance before reaching production, where measuring continues.
Follow a change end to end on the diagram. It enters through the repository, written by a person or by an agent working with rules and permissions. It goes through deterministic tests and guardrails. If it touches anything related to a model, it goes through evals with their dataset and calibrated judge. Before release, through security and performance. In production it stays measured with traces and online evals, and every failure returns to the regression set. The closed loop is what makes the system improve with use.
2. An honest checklist
Fill in the checklist honestly. "I saw it in a video" doesn't count; what runs in a repo does.
Fill in the twelve-piece checklist with a strict rule: a piece counts only if it runs in a repository and someone uses it. Having read about it, seen it in a video or tried it one afternoon doesn't count. The rule is uncomfortable, and that's why it works. Most teams discover they have two or three real pieces and several half done. That isn't a bad result. It's a precise starting point, and it's what you need to plan without fooling yourself.
3. Three pieces, by risk
Pick three missing pieces and order them by your product's risk, not by what's most fun.
From the missing ones, pick three and order them by your product's risk, not by what you find most interesting. If your system has a tool-using agent and there are no injection tests, that goes before optimizing costs. If a feature with a model is in production with no eval at all, that goes first. Ask yourself which failure would hurt you most tomorrow and which piece would have caught it. That's the first one.
4. A ninety-day plan
Build the 90-day plan: one piece per month, each with a verifiable deliverable.
Assign one piece per month, each with a verifiable deliverable. "Learn about evals" isn't a deliverable. "A thirty-case eval for the classifier, running in the PR pipeline" is. One month per piece looks slow. It's realistic if you do it alongside your usual work. Put the dates on the calendar and tell someone on your team about the plan. A commitment another person knows about gets kept far more often than a private one.
5. Publish evidence
Publish evidence: the repo with a README explaining what each part measures, and a written case with your own numbers.
As you finish each piece, leave it visible. A repository with a README explaining what each part measures and how to run it. A written case with your own numbers: what the problem was, what you measured, what you decided and what happened next. Use your own or synthetic data, never a client's information. That evidence works inside your team, so others adopt what you built, and outside it, because it shows applied judgment and not just knowledge of tools.
6. Back to the matrix
Update the day 2 matrix and set a date to repeat the self-assessment.
Open the skills matrix from day two and update it with what you did this month. Rows that were at zero or one should now have linked evidence. Set a date to repeat the self-assessment three months from now, when the plan ends. The specific tools in this series will change, some within a few months. What holds is the method: define what correct means, measure it repeatably and decide with data.
Illustrative example
An SDET fills in the checklist at the end of the series. Real pieces: the delegation rule, a repo with rules for agents and the TDD cycle with guardrails. Half done: an eval run by hand. Missing: everything else. Her product has an assistant with access to customer data and an email tool. She orders by risk. First month, injection tests on the agent's actions. Second month, the eval with a versioned dataset inside the pipeline. Third month, traces and a quality alert in production. She leaves cost and performance for the following quarter, and writes that down as a decision, not an oversight.
Common mistakes
- Marking as done a piece you only saw or tried once.
- Choosing what to build by interest and not by product risk.
- Planning all twelve pieces for the same quarter.
- Publishing evidence with a client's data or details.
Checklist: how to know it is done
- The checklist is filled in under the rule that only what runs counts.
- Three pieces are chosen and ordered by risk.
- The ninety-day plan has one verifiable deliverable per month.
- The day two matrix is updated and has a review date.
Where AI fell short
It summarizes well and doesn't prioritize. Deciding which risk comes first in your product is still a person's job.
Frequently asked questions
Where do I start if my product doesn't use AI yet?
With the pieces that improve your current work: the delegation rule, the repo with rules for agents and TDD with guardrails. The rest stays as preparation for when your product takes on a model, which tends to happen sooner than planned.
Is all of this needed in a small team?
Not all of it. A small team with one AI feature needs, at minimum, an eval with a versioned dataset in the pipeline, and controls on actions if there is an agent. The rest gets added as risk grows.
Will the guides go out of date?
The commands and versions will, which is why each guide states when it was reviewed. The concepts change far more slowly: dataset, scorers, threshold, gate, least privilege and traces will remain the base with any tool.
Day 31 of 31 of the 31 days of QA + AI series. Commands and versions reviewed in November 2026: rerun them before relying on them, AI tooling changes fast.
← Previous: LLM observability in production: traces, online evals and alerts