Guide · QA + AI series · 30/31 · November 13, 2026 · 7 min read
LLM observability in production: traces, online evals and alerts
What to record for every production model call, how to continuously evaluate a sample and which alerts justify waking someone up.
Everything you tested before release describes how the system behaved with your cases, in your environment, on that day. In production, inputs nobody imagined arrive, the provider updates the model, documents change and users find new uses. An AI system can degrade without anyone having deployed anything.
That's why quality in these systems doesn't end at the gate. It continues in production, with the same questions and different instruments: traces instead of reports, evals on real traffic instead of datasets, alerts instead of CI thresholds. This guide builds that circuit and closes it, so that every failure found in production comes back as a test case and doesn't repeat.
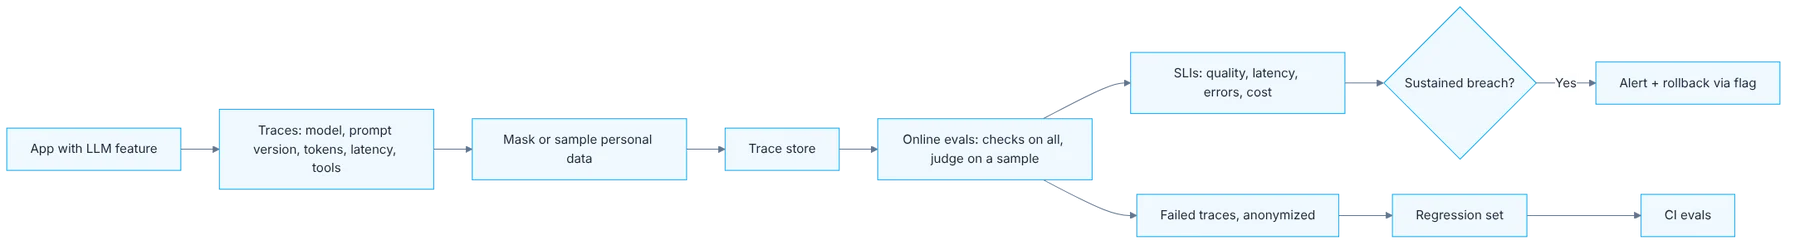
How it fits together
Show the diagram as text
app with LLM feature
   ▼
traces: model · prompt version · tokens · latency · tool calls
   ▼
mask / sample personal data ▶ trace store
   ▼
online evals: checks on all traffic, judge on a sample
   ├─▶ SLIs: quality · latency · errors · cost ▶ sustained breach? ▶ alert + rollback via flag
   └─▶ failed traces, anonymized ▶ regression set ▶ CI evals
Requirements
- An LLM feature in an environment with traffic (staging works).
- An LLM tracing tool; Langfuse is open source and can run locally.
- The scorers from the eval harness (days 8 and 16).
Setup
git clone https://github.com/langfuse/langfuse.git
cd langfuse && docker compose up -d
What to record and what to measure
- Requested model and responding model:
gen_ai.request.modelandgen_ai.response.model(OpenTelemetry GenAI conventions). - Input and output tokens:
gen_ai.usage.input_tokensandgen_ai.usage.output_tokens. - Operation:
gen_ai.operation.name. - Prompt version, total latency and time to first token: custom attributes and the span duration.
- Tool calls and outcome: child spans.
- Quality indicator: pass rate of online evals. Alert on a sustained drop, not an isolated point.
- Latency indicator: TTFT p95, per the day 25 target.
- Error indicator: 429, 5xx and timeouts below the agreed maximum.
- Cost indicator: hourly spend against the daily budget.
Step by step
1. One span per model call
Instrument every model call as a span with model, prompt version, tokens, latency and outcome. The OpenTelemetry GenAI conventions give you the names.
Instrument every model call as a span recording which model was requested and which one answered, the prompt version, input and output tokens, latency and outcome. The OpenTelemetry conventions for generative AI define standard names for those attributes. Using them avoids inventing your own schema and lets you change observability tools without re-instrumenting. Tool calls and a RAG's searches go as child spans, so you can see the full chain behind an answer.
2. What gets stored and for how long
Mind what you store: prompts and responses can carry personal data. Mask or sample, and set retention.
Prompts and responses can contain personal data, and a full trace stores them in plain text. Decide explicitly what gets stored. The options are masking sensitive fields before saving, storing full content only for a sample, or keeping only metadata by default. Also define a retention period and who has access. It's a decision to make together with security and legal, and it's best made before instrumenting.
3. Online evals
Online evals: run deterministic checks on all traffic and the judge on a sample. They're the same scorers you use in CI.
The same scorers you use in CI can run on real traffic. Deterministic checks, for format, required fields and lengths, are cheap and apply to every response. The judge costs tokens, so it applies to a sample. The result is a continuous pass rate on what users really receive. It's the signal that warns you of a degradation no dataset could anticipate, because it comes from inputs you didn't have.
4. Four indicators with alerts
Define four indicators (quality, latency, errors and cost) with a target and an alert. Alert on sustained trend, not on one case.
Define four indicators, each with its target and its alert. Quality: the pass rate of online evals. Latency: time to first token at the ninety-fifth percentile. Errors: quota limits, server errors and timeouts. Cost: hourly spend against the daily budget. Alerts are configured on sustained trend, not on an isolated case. With a system that varies by nature, alerting on every bad response generates noise until nobody looks.
5. Closing the loop
Close the loop: every production failure, anonymized, joins the regression set.
Every failure found in production, through an alert, an online eval or a user complaint, gets anonymized and added to the regression set. This step turns observability into improvement. Without it, the same kind of failure returns with the next prompt change. With it, your dataset looks more and more like real usage. Assign an owner and a cadence: review the week's failures and decide which ones go in.
6. The rollback plan
Have the rollback plan written: pinned prompt and model versions and a flag to return to the previous version without a deploy.
Have it written down how to go back before you need it. It requires three things: the prompt and model versions pinned and recorded, the previous version still available, and a flag that lets you go back without a deploy. Try the rollback once, in a test environment. A plan that was never executed tends to fail at the worst moment. When the quality alert fires, the first action must be returning to a known state, and analysis comes afterwards.
Illustrative example
A support assistant has been in production for two months with traces and online evals. One Thursday, the judge's pass rate on the sample drops steadily for three hours, with no deploy. The quality alert fires. Traces show the model answering has a different identifier from last week's: the alias they used pointed to a new version. They flip the flag back to the previous pinned version and the rate recovers. Then they anonymize twelve failed conversations, add them to regression and run the full eval against the new version before deciding whether to adopt it.
Common mistakes
- Storing full prompts and responses with no masking or retention policy.
- Alerting on every failed response instead of on trend.
- Recording only the requested model and not the one that answered.
- Not adding production failures to the regression set.
Checklist: how to know it is done
- Each model call generates a span with model, prompt version and tokens.
- There is a written policy for masking, sampling and retention.
- Online evals run with deterministic checks and a judge on a sample.
- The flag-based rollback was tried at least once.
Where AI fell short
The model that answers may not be the one you requested if you use an alias. Record both or you won't be able to explain a behavior change.
Frequently asked questions
What share of traffic should go through the judge?
Whatever your budget allows and is enough to see a trend within a few hours. Start with a small sample and raise it if the indicator turns out too noisy. Deterministic checks, on the other hand, go on all traffic.
Do I need an LLM-specific observability tool?
It helps, because it shows prompts, responses and costs conveniently. But if you instrument with standard conventions, you can start with the tracing tool you already use and switch later without touching code.
How do I tell real degradation from noise?
With time windows and comparison against the baseline, just as on day eighteen. A drop that holds across several consecutive windows and exceeds usual variation is a signal. A single low point isn't.
Day 30 of 31 of the 31 days of QA + AI series. Commands and versions reviewed in November 2026: rerun them before relying on them, AI tooling changes fast.
← Previous: QA infra for AI: ephemeral runners, local models, secrets and cost
Next: Capstone: the full AI quality pipeline and your 2027 roadmap →