Guide · QA + AI series · 17/31 · November 13, 2026 · 6 min read
Golden datasets: how to label, balance and version
A small but reliable golden dataset: with a labeling guide, three splits and Git versioning.
Everything we measured over the last few days depends on a piece that usually gets little attention: the set of cases with their correct answer. If the labels are wrong, the best harness in the world measures the wrong thing precisely. If the set has only easy cases, any model looks excellent. And if cases leak into the prompt, the number stops meaning anything.
A golden dataset is that set treated with the care a measuring instrument deserves. This guide covers how to gather the cases, how to label them with shared criteria, how to balance them, how to split them so you don't fool yourself and how to version them. It's craft work, and it's what most improves the quality of every later decision.
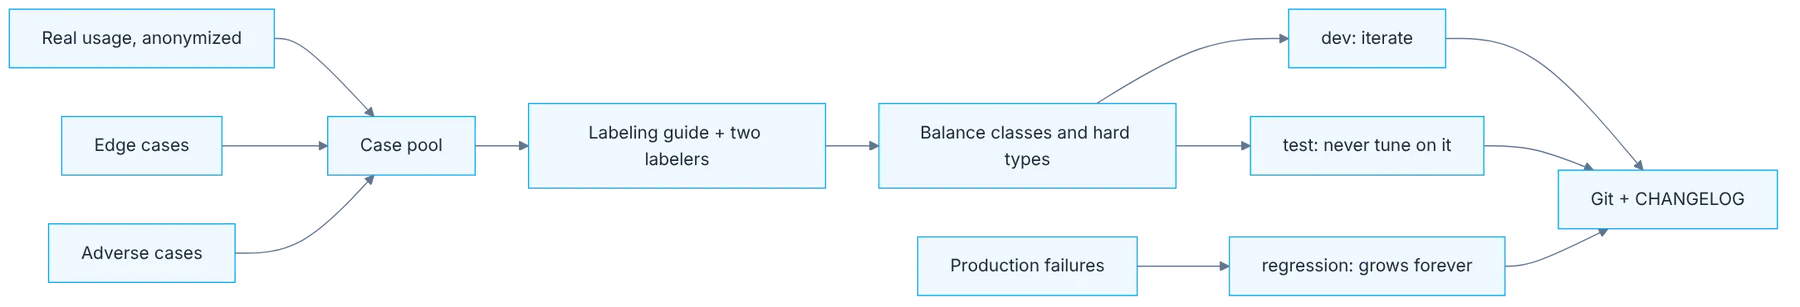
How it fits together
Show the diagram as text
real usage (anonymized) ─┐
edge cases ──────────────┼─▶ case pool ▶ labeling guide + two labelers ▶ balance
adverse cases ───────────┘                                                  │
                                 ┌──────────────────────────────────────────┤
                                 ▼                                          ▼
                          dev (iterate)                     test (never tune on it)

production failures ─▶ regression (grows forever)

dev · test · regression ─▶ Git + CHANGELOG
Requirements
- The
qa-ai-labrepo,data/folder. - 50 to 100 anonymized real or synthetic cases.
- Ideally, a second person to label a sample.
Setup
{"id":"case-001","input":"ACME Intl. Corp","expected":"map_to_existing:ACME","tags":["abbreviation"],"labeler":"gg","label_version":2}
{"id":"case-002","input":"N/A","expected":"map_to_other","tags":["filler"],"labeler":"gg","label_version":1}data/
golden/dev.jsonl # iterate prompts here
golden/test.jsonl # never used to tune, never quoted in prompts
golden/regression.jsonl # every case that failed in the past
LABELING_GUIDE.md
CHANGELOG.mdStep by step
1. Three sources of cases
Collect cases from three sources: anonymized real usage, edge cases and adverse cases (filler, duplicates, empty inputs).
The first source is real usage, anonymized: it shows what inputs are really like, with their typos and ambiguities. The second is the edge cases you know exist even though they rarely show up: boundary values, odd formats, very long inputs. The third is adverse cases, designed to cause trouble: filler text, duplicates, empty inputs or ones in another language. A dataset built only from the first source describes the average and says nothing about the failures.
2. The labeling guide
Write the labeling guide: definition of each label, two examples per label and what to do when in doubt.
Before labeling in volume, write a short guide: the definition of each label, two examples per label and what to do when in doubt. That last part is the one most often forgotten. Without a rule for doubtful cases, each person resolves them differently and the dataset piles up inconsistencies. The guide also forces business decisions that were implicit. If writing a label's definition proves hard, the system probably can't apply it either.
3. Two people, twenty cases
Two people independently label a sample of 20. Where they disagree, the guide is incomplete: fix it.
Take a sample of twenty cases and have two people label it separately, without seeing each other's answers. Then compare. Disagreements aren't the people's errors: they're gaps in the guide. Discuss each one, decide and update the guide with the new rule or an example. Repeat until disagreements are few. Only then is it worth labeling the rest. That agreement between people also marks the reasonable ceiling for any model.
4. Balance
Balance: every class and every hard type must be represented. If 90% is easy, your accuracy lies.
Count how many cases there are per class and per difficulty type. If ninety percent is easy, a system that solves only the easy part scores ninety and looks ready for production. Each class and each hard type needs enough representation for its hit rate to mean something. That implies over-representing rare cases on purpose. That's fine: an evaluation dataset doesn't aim to mirror production proportions, but to expose where the system fails.
5. Three splits
Split in three: dev to iterate, test never used for tuning nor quoted in prompt examples, and regression with everything that ever failed.
Split the set in three. Dev is for iterating: there you try prompts and look at failures as often as you like. Test isn't used for tuning anything nor quoted in prompt examples, and is consulted only to make a decision. Regression collects everything that ever failed and got fixed, so it doesn't come back. Discipline with test is the hard part. Every time you adjust something while looking at those results, it stops measuring how the system will behave on new cases.
6. Versioning
Version as JSONL with a CHANGELOG. Fixing a label is a commit, and after a fix you recompute earlier metrics.
Store each split as JSONL, one case per line with a stable identifier, and keep a CHANGELOG. Fixing a label is a commit with its reason, just like a code change. After a fix, earlier metrics must be recomputed, because the instrument changed and the old numbers are no longer comparable. Note the dataset version on each run card. Without that fact, a two-point improvement may be nothing more than a corrected label.
Illustrative example
A team builds a dataset for a system that decides whether a new supplier already exists in the catalog. They gather one hundred and twenty cases: sixty from anonymized real usage, forty edge cases and twenty adverse. Two people label twenty and disagree on six. The origin is a single unanswered question: whether a branch counts as the same supplier. They decide it, add it to the guide and disagree on one in the second round. Counting, they discover only eight cases are of the "nearly identical name, different company" type, the costliest error. They add twelve more. They split into sixty dev, forty test and twenty regression.
Common mistakes
- Letting the model generate the labels it's evaluated against.
- Labeling everything with a single person and no written guide.
- Tuning the prompt while looking at test set results.
- Fixing labels with no record and comparing old metrics with new ones.
Checklist: how to know it is done
- The dataset has real, edge and adverse cases.
- There is a labeling guide with a rule for doubtful cases.
- Two people labeled a sample and resolved their disagreements.
- Dev, test and regression exist as JSONL with a CHANGELOG.
Where AI fell short
A model graded against labels it generated always looks good. Test labels come from a person.
Frequently asked questions
How many cases does a golden dataset need?
Enough for each class and each hard type to have several cases. For many classification tasks, one to three hundred well-chosen cases serve better than thousands picked at random. Label quality and balance weigh more than volume.
Can I use a model to help with labeling?
To propose a first label that a person reviews, in the dev split, it can save time. In test, the final label must come from a person. Otherwise you're measuring how much one model resembles another.
How do I anonymize real usage cases?
Replace names, ID numbers, emails and any identifier with synthetic values in the same format, and review free-text fields by hand. If a case can't be anonymized without losing what makes it interesting, write an equivalent one from scratch.
Day 17 of 31 of the 31 days of QA + AI series. Commands and versions reviewed in November 2026: rerun them before relying on them, AI tooling changes fast.
← Previous: LLM-as-a-judge: rubrics and calibration against humans