Guide · QA + AI series · 15/31 · November 13, 2026 · 6 min read
How to set up models for quality testing
Configuring a model for testing reproducibly: pinned version, explicit parameters, structured output and a judge separate from the model under test.
When a test involving a model gives different results from one day to the next, the first suspect is usually the model. The second should be the configuration. An alias pointing to the latest version, a temperature left at its default, a token limit that cuts the answer off or a judge that changed without notice explain a good share of the unexplained differences.
Setting up a model for quality testing means treating it like any other dependency of a test environment: pinned version, explicit parameters and a record of what each thing ran with. This guide walks through the six decisions that make two runs comparable, and makes clear what reproducibility means when the system under test isn't deterministic.
How it fits together
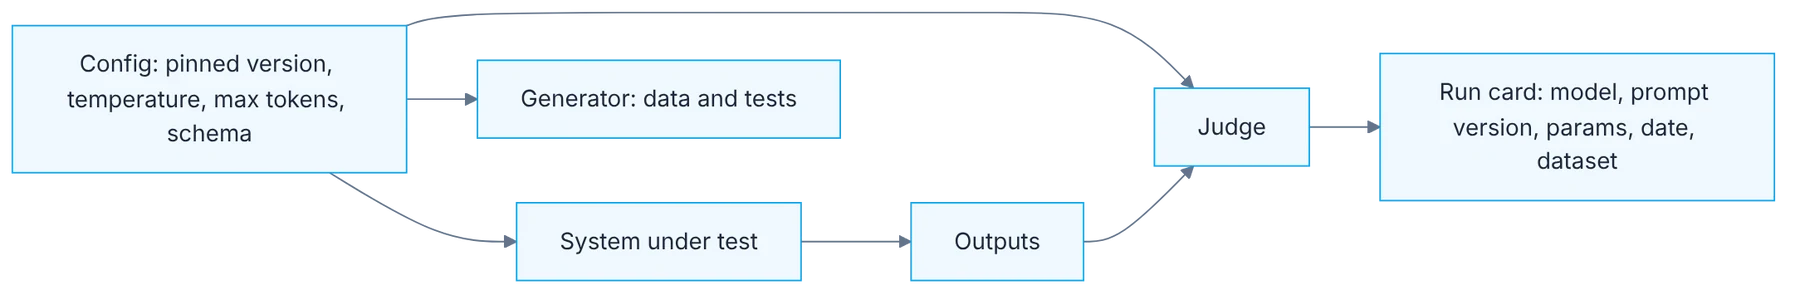
Show the diagram as text
config: pinned version + temperature + max tokens + schema
   ├─▶ system under test ──▶ outputs ──┐
   ├─▶ generator (data / tests)        │
   └─▶ judge ◀─────────────────────────┘
          ▼
   run card: model · prompt version · params · date · dataset
Requirements
- The eval harness from day 8.
- Optional: a provider API key for the second model and the judge.
Setup
providers:
  - id: ollama:chat:llama3.2
    label: sut-small
    config:
      temperature: 0
  - id: openai:chat:YOUR_PINNED_MODEL_ID
    label: sut-large
    config:
      temperature: 0
      max_tokens: 300

defaultTest:
  options:
provider: openai:chat:YOUR_JUDGE_MODEL_ID # grader for llm-rubric assertsStep by step
1. The role defines the config
Define the model's role in the test: system under test, generator (data or tests) or judge. Each role is configured differently.
The same model can play three roles in your process, and each asks for something different. As the system under test, it's configured the same as in production, because you want to measure what the user gets. As a generator of data or tests, it can use more temperature to produce variety. As a judge, it needs the most stable configuration possible. Mixing roles in a single config is a frequent mistake: you end up measuring the product with parameters the product doesn't use.
2. Exact version, no aliases
Pin the exact version. No "latest" aliases: if the provider updates the model, your results change without you touching anything.
Providers offer aliases pointing to a model's most recent version. They're convenient for development and bad for measuring: the day the alias moves, your results change without you touching anything, and you have no way of knowing why. Always use the full identifier with its version or date. When you want to upgrade, do it as a deliberate change: run the eval with the old and the new version, compare, and only then change the identifier.
3. Parameters in plain sight
Explicit parameters: low temperature for classifying and judging, an output token limit and a seed if the provider supports it. If a model doesn't expose a parameter, write that down.
Write into the config the parameters that affect the output, even when they match the defaults: temperature, output token limit and seed if the provider supports it. For classifying and judging, low temperature. The token limit deserves attention: an answer cut off halfway can look like a format failure when it's a badly set limit. Some models don't expose certain parameters or ignore them. Note that too, so you don't credit the config with control you don't have.
4. Structured output
Structured output: request JSON with a schema. It removes a good share of your format failures.
If your code is going to parse the answer, request it as JSON with a schema, using the provider's structured output mechanism where one exists. It reduces a whole class of failures: text before or after the JSON, fields with another name, values outside the allowed list. It doesn't replace validation on your side, which is still necessary, but it changes the proportion. You'll spend evals measuring whether content is correct, instead of spending cases discovering the format came back broken.
5. A separate judge
Separate judge: the grading model shouldn't be the one being graded, and should be equally or more capable.
The model that grades shouldn't be the one being graded, and it should be equally or more capable. A model evaluating its own output tends to find it reasonable, because it shares the same biases that produced it. Declare it as a separate provider, with its pinned version and its label. Changing the judge is changing the measuring instrument: after doing so, new metrics aren't comparable with earlier ones until you recalibrate.
6. The run card
Record a run card for each run: model and version, prompt version, parameters, date and dataset. No card, no valid comparison.
Each run should leave a record with model and version, prompt version, parameters, date, dataset and, if any, judge. It's a small file stored next to the results. Without that card, a comparison between two runs says nothing, because you don't know what else changed between them. With it you can answer the question that always arrives: why it scored ninety last week and eighty-four today.
Illustrative example
A team notices their classification eval dropped five points with nobody touching the prompt. They look for the run cards and there are none. They reconstruct what they can: the provider used an alias and the vendor had released a new version that week. They pin the previous version, run again and the result returns to its original value. Then they run the new version on purpose: it's better on ambiguous cases and worse on two critical ones. They decide not to upgrade yet. From then on, every run stores its card and the model identifier includes the date.
Common mistakes
- Using a version alias in evals or in CI.
- Evaluating the product with parameters different from production.
- Using the model under evaluation as its own judge.
- Comparing two runs without knowing what changed between them.
Checklist: how to know it is done
- Each provider has a role and a label that states it.
- Every model is pinned to an exact version.
- Temperature, token limit and seed are written down.
- Each run stores its card next to the results.
Where AI fell short
Temperature zero doesn't guarantee the same answer. Reproducibility with LLMs is statistical: you measure it with repeated runs.
Frequently asked questions
With temperature zero and a seed, do I always get the same thing?
Not guaranteed. It reduces variation, but hardware, provider updates and parallel processing can produce differences. That's why reproducibility with models is measured with several runs and ranges, not taken for granted.
How often should I upgrade the model version?
When you have a reason: better quality, lower cost or a version being retired. Check the retirement dates the provider publishes so you don't find out on the day. Every upgrade goes through the eval first.
Is a local model configured the same way?
Yes, with one detail: the version is the model's exact tag and also its quantization. Two downloads under the same general name can be different files. Note the full identifier on the card.
Day 15 of 31 of the 31 days of QA + AI series. Commands and versions reviewed in November 2026: rerun them before relying on them, AI tooling changes fast.
← Previous: TDD with AI (2): guardrails so the agent can't cheat
Next: LLM-as-a-judge: rubrics and calibration against humans →